
BENCHMARK · V4
BOM AI v4 Benchmark — Thai AI Quality Test Results
Tested with 70 real questions covering: vision · Thai chat · translation · chart reading · Chinese-leak checks — full score 70 points.
🏆 v4 Scores
Mega QC task scores out of 10: chat, search, vision, think, stress, safety. A dash means that task was not scored.
| Model | Chat | Search | Vision | Think | Stress | Safety | Note |
|---|---|---|---|---|---|---|---|
| BOM AI Light (Qwen3.5 4B) | 7.5 | 7.5 | 9.5 | 8 | 10 | 10 | best all-rounder |
- BOM AI Light (Qwen3.5 4B) is the best all-rounder and reads images
Have a GPU = very fast · No GPU = still works
Pick the one that matches your hardware:
- BOM AI Light (Qwen3.5 4B) — 8 GB RAM or CPU — Lightweight, reads images
🔐 Use it from your phone via Tailscale VPN
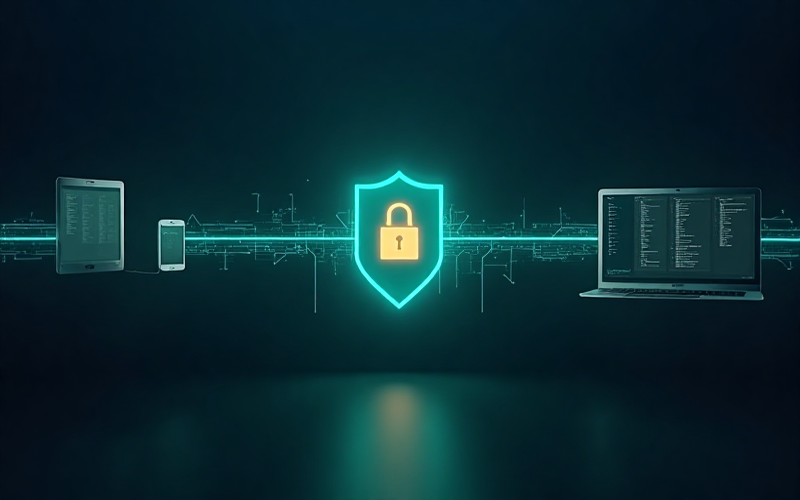
Install Tailscale (free) on your phone + the computer running BOM AI, then access your AI from anywhere in the world
- Secure — only you can get in
- No ports to open, no hacking exposure
- Private VPN — nobody gets in even if they know your IP
📋 Minimum Specs
What your computer needs to run BOM AI
| Item | Minimum | Recommended |
|---|---|---|
| RAM | 8 GB | 16 GB+ |
| Disk space | 10 GB | 10 GB+ |
| GPU (VGA) | Not required | NVIDIA 4 GB+ |
| Operating system | Windows 10/11 64-bit | — |
⏳ Status: final-round testing on macOS + Linux and fine-tuning the best configs before release
METHOD — internal test, Oct 2026 · 70 real questions · scored against answer criteria · full score 70
⚖️ BOM AI vs ChatGPT
The honest comparison - different tools, different strengths
| Item | BOM AI | ChatGPT |
|---|---|---|
| Price | Free, forever | About $20/month (Plus plan) |
| Limits | Unlimited use | Usage caps depend on plan |
| Privacy | Runs 100% on your computer | Chats stored on company servers |
| Offline | Offline for chat, vision & translation (web search uses the internet only while searching) | Requires internet |
📋 Methodology & Dataset Card
| Purpose | Measure how well each BOM AI edition handles real Thai everyday tasks on a normal computer. |
| Sample | Fixed set of n = 70 questions (vision, Thai chat, translation, chart reading, Chinese-leak checks) plus 6 Mega QC task axes (chat, search, vision, think, stress, safety) scored 0–10. |
| Model versions | BOM AI v4 — Light (Qwen3.5 4B), build tested 2026-10-29. |
| Hardware | Developer machines matching the classes on the Requirements page (CPU with 8 GB RAM, and NVIDIA GPU class). Per-run hardware log will be attached from the next release. |
| Evaluator | Internal developer self-test by the BOM AI team — not an independent laboratory. |
| Rubric | 70-question set: 1 point per correct answer (full score 70). Task axes: checklist scored 0–10 per axis. |
| Costs | Free to reproduce with the public installer; no paid API is used for BOM AI runs. |
| Exclusions | Languages outside the task mix, multi-user setups, and contexts longer than 8k tokens were not scored. |
| Limitations | Small internal sample, single-evaluator bias is possible, scores change between versions, and the ChatGPT price comparison was checked on 2026-11-01. No "best model" guarantee beyond these tasks. |
| License & data | Results © BOM AI. The question set and raw run logs are available on request. |
| sha256 | Installer hashes will be published with the next signed release. |
| checked_at | 2026-11-01 |